
BEP Research · one chart
Cheaper tokens are not the whole investment case.
A token quote is one input. The question is what accepted work costs—and who captures the value.
The video’s text is visible on screen. A text summary, downloadable chart, and full methodology follow.
The observation
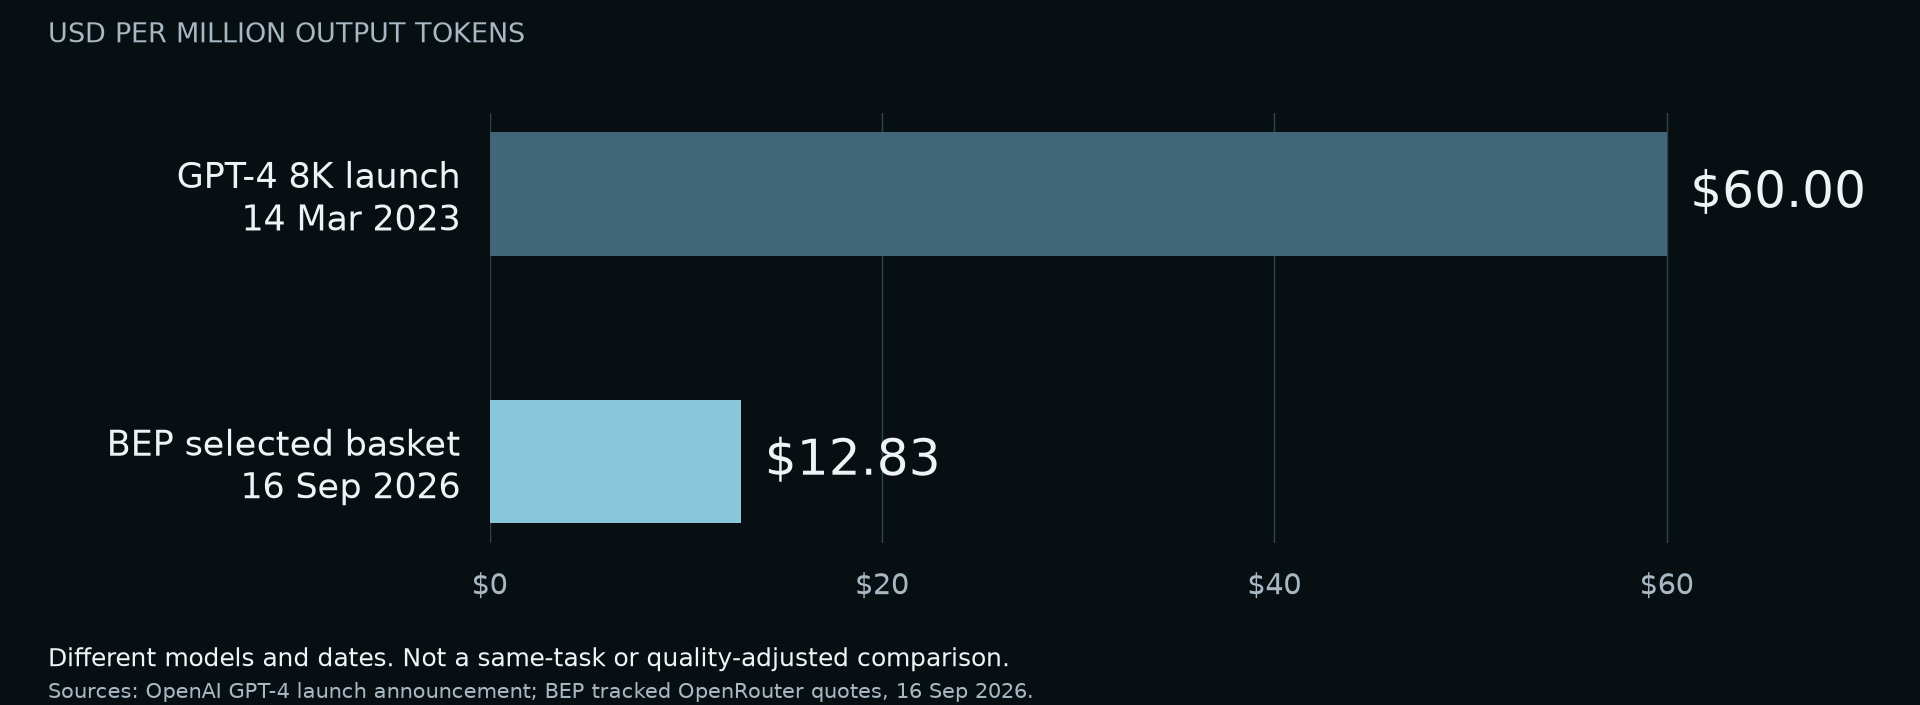
$60.00 versus $12.83 per million output tokens.
GPT-4’s 8K-context model launched on March 14, 2023 with an output price of $60 per million tokens. BEP’s selected price basket is $12.827 on September 16, 2026, displayed here as $12.83. That is about 79% lower in quoted output price.
These are different models and dates. This is not a same-task or quality-adjusted comparison, and does not show that a real workload became 79% cheaper.
From observation to decision
Measure the cost of accepted work.
For a defined workload, add input and output charges, retries, tool calls, and human review. Divide total measured cost by accepted results under the required quality and latency targets. That produces a decision-relevant cost measure; a token quote alone does not.
Then examine whether lower costs become customer discounts, provider margins, or additional usage. This chart supplies no direct evidence of demand growth, company profits, or investment returns. The next study needs repeatable task tests and permissioned customer bills.
Reproduce the number
What BEP selected on this date.
| Component / model | Weight | $/M output |
|---|---|---|
| OpenAIopenai/gpt-5.4 | 30% | $15.00 |
| Anthropicanthropic/claude-opus-4.6 | 25% | $25.00 |
| Googlegoogle/gemini-2.5-pro | 20% | $10.00 |
| DeepSeekdeepseek/deepseek-v3.2 | 15% | $0.40 |
| open-sourceopenai/gpt-oss-120b | 10% | $0.17 |
Fixed provider-priority selection; cheapest positively priced tracked named open-weight family for the final component. Observed weights are rescaled if components are missing. Not a newest-flagship guarantee or all-model average.
All five components are observed in this snapshot. The weighted sum is $12.827; dividing by the $60 reference and multiplying by 100 gives 21.3783 index points, displayed as 21.38.
- Different models and dates; not a same-task or quality-adjusted cost comparison.
- Output token quotes only; input, retries, tools, human review, caching and negotiated discounts are excluded.
- OpenRouter tracked list quotes are not necessarily vendor-direct or transacted prices.
- The comparison does not measure profit, demand or investment returns.
This is a dated briefing. The public live observation can change as later snapshots arrive; the source file for this briefing remains fixed.
Sources and text version
- OpenAI: GPT-4 launch announcement — original 8K output quote, March 14, 2023.
- OpenRouter model catalog — source of the tracked quotes, captured in BEP’s September 16 snapshot. Current catalog prices may differ.
- BEP’s dated selections and source record — captured 2026-09-16T10:49:50.962Z.
Read the briefing
A lower token quote is a starting point. The research question is the cost and value of useful work.
$60.00 versus $12.83 per million output tokens. Launch price versus the BEP selected basket; different models and dates.
About 79% lower quoted output price. Not evidence that the same workload became 79% cheaper.
Fixed weights and model-priority rules. Not every model, not always the newest flagship.
Include input/output, retries, tool calls, and human review. Compare at the same quality and latency target.
Cheaper output tokens alone do not establish demand growth, realized margins, or investment returns.
Next: repeatable task tests plus permissioned customer bills. Read the source notes at BEP Research.
Follow the evidence with BEP.
Research connecting models, infrastructure, and the economics behind long-term investment.